AI Readiness Blog
Practical guides on making your website discoverable, parseable, and actionable for AI agents and LLM-powered search.
"Multiple H1 Tags" Warning: What It Breaks for AI Crawlers, and How to Fix the Theme That Adds the Second One
Several <h1 elements will not get your page penalised by Google, and Google's own documentation says so. What they do break is extraction: an agent that takes the first <h1 as the page title reads…
Set X-Robots-Tag or a Canonical Link Header on .md Copies and llms.txt: Nginx, Apache, Cloudflare, Vercel, Netlify, Next.js, Astro
Send one header on each .md copy and nothing new on the HTML: Link: <https://example.com/page; rel="canonical". On /llms.txt, which has no HTML twin, the only header that applies is XRobotsTag:…
Should Google Index Your llms.txt and .md Copies? Our Search Console Data (2026)
No, and on our own site Google is not even trying. On 13 November 2026 we asked Search Console about 15 machinereadable copies on aiscan.site: /llms.txt, /llmsfull.txt, /index.md and twelve .md…
Do noai and noimageai Meta Tags Stop AI Crawlers? What Each Vendor's Docs Say (2026)
No. On 12 Nov 2026 we read the crawler documentation of eight AI operators OpenAI, Anthropic, Google, Apple, Perplexity, Common Crawl, Amazon and Microsoft and none of them documents noai or…
Publish an A2A Agent Card at /.well-known/agent-card.json, Tested on Every Stack
An A2A Agent Card belongs at /.wellknown/agentcard.json, served as application/json, with eight required toplevel fields filled in. The older path, /.wellknown/agent.json, came from A2A 0.2.x and was…
Why robots.txt Checkers Disagree About GPTBot: 5 Parsers, 15 Files, Tested (2026)
Robots.txt checkers disagree about GPTBot because each one is built on a parser library, and the libraries do not agree on the rules. We ran 15 small robots.txt files through five parsers that…
Google-Extended Allow Overrides Your __usage_ai-training Opt-Out: The Precedence Table
If your robots.txt has a GoogleExtended group with Allow: /, adding the new usageaitraining optout does nothing at Google. Google said on 30 Oct 2026 that it will read the token as a GoogleExtended…
Add the __usage_ai-training Token on 10 Platforms (Tested 2026)
To add the usageaitraining token, put a separate UserAgent: usageaitraining group in whatever file or setting actually produces your robots.txt: a template on Shopify, an editor on Wix and Webflow, a…
The __usage_ai-training robots.txt Token, Tested in 3 Parsers (2026)
usageaitraining is a robots.txt "policy token": you write UserAgent: usageaitraining followed by Disallow: and Allow: paths, and participating AI companies read that group as your preference about AI…
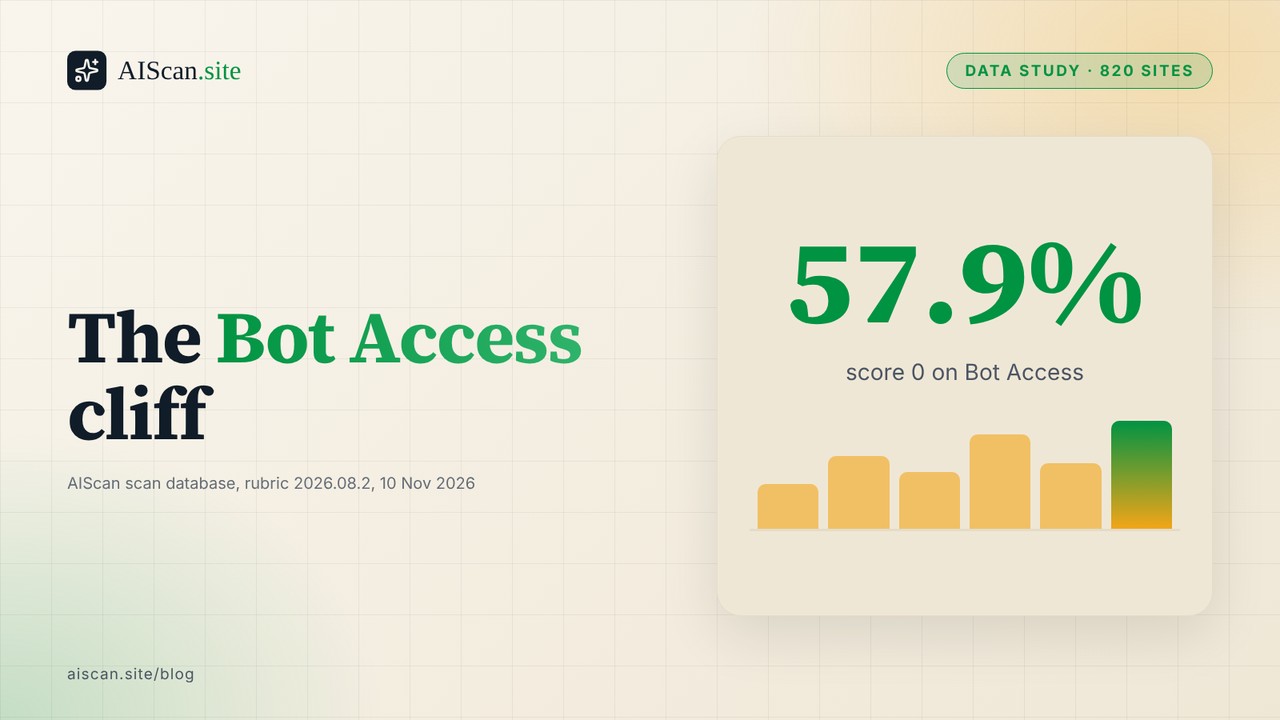
Bot Access Scores 0 on 58% of 820 Sites, and One Check Decides It
Of 820 hosts in the AIScan corpus, 475 57.9% score 0 on the Bot Access dimension and 263 32.1% score 100. Only 82 sit anywhere between. The dimension is close to a coin flip, and the coin is a single…
Canonical host redirects on Next.js, Webflow, Squarespace, Lovable, Replit, Framer and Wix
If example.com and www.example.com both return your site, every page exists twice. The fix is one rule: pick a host, then send the other one to it with a redirect. On a hosted builder that rule is a…
Python's robots.txt Parser Treats a 403 as Disallow-All: Fix the False "Blocked" Result
A robots.txt that answers 401 or 403 to your script does not mean "closed" to most crawlers. RFC 9309 says a 4xx robots.txt is "unavailable" and the crawler MAY access any resource. Python's…
Test Every Page Template for AI Crawler Access, Not Just the Homepage: A Python Probe Script
A homepage that answers GPTBot with a 200 tells you nothing about the page templates behind it. A firewall rule, a CDN path rule or a plugin can block /products/, /docs/ or the feed while / stays…
Why AI Rules Vanish From robots.txt: 25 of 144 Passing Sites Lost Them
Of 144 hosts that passed the AIcrawler robots.txt check B2 on their first scan, 25 failed it on their latest scan. All 25 had exactly 8 known AI agents named in robots.txt the first time and 0 the…
What Happens When a Site Is Scanned Again: 616 Hosts, 170 Improved, 73 Got Worse
Of 616 hosts in our scan corpus that were scanned more than once, 170 scored higher on their latest scan than on their first, 73 scored lower, and 373 did not move. The median change is 0 points and…
MCP Server Cards on 808 Sites: 32 Pass, and 52 of 65 Partials Fail E1
Of 808 hosts in our scan corpus, 32 pass check P2, the MCP server card check. Another 65 answer HTTP 200 at the card path and earn only partial credit, and 52 of those 65 also fail our soft404 check.…
"Syntax not understood" on Content-Signal in Search Console: what it means and whether to fix it
If Google Search Console shows "Syntax not understood" next to a ContentSignal: search=yes, aitrain=no line in your robots.txt, nothing is blocked and you do not need to fix anything. In a local test…
Scan a site from Claude with the AIScan MCP connector
You can run an AIScan audit without leaving a chat. Add https://aiscan.site/mcp as a remote MCP connector in Claude or in any client that accepts a remote MCP URL, sign in with your AIScan account…
OAuth Discovery Metadata on 806 Sites: 133 Pass, and 47 of 50 Soft 200s Fail E1
Of 806 hosts in our scan corpus, 133 pass check P4, the OAuth discovery check. That is 16.5%. The more useful number is 50. fifty hosts answered HTTP 200 at an OAuth metadata path and still did not…
Fix: your OAuth protected-resource metadata is at the wrong path for MCP clients
An MCP client that gets a 401 from https://api.example.com/mcp has to find your OAuth metadata somewhere, and RFC 9728 gives it two places to look: /.wellknown/oauthprotectedresource/mcp the…
Log the Requests to Your MCP Server: Who Called, Which Tool, What Failed
If you want to know who calls your MCP server, which tool they ask for and what failed, log one JSON line per HTTP request and read the outcome from the response body, not only the status code. In…
Fix: A WordPress Security Plugin Is Blocking GPTBot, ClaudeBot and PerplexityBot
If your robots.txt allows GPTBot, ClaudeBot and PerplexityBot but your logs show a wall of 403 for those same names, robots.txt is not the problem. A rule that runs before WordPress is. This guide…
How to serve text/markdown to AI agents on every stack
An AI agent that sends Accept: text/markdown gets your HTML unless the server answers differently. Check C1 grades that exact request, and no staticsite generator or Next.js app does it by default.…
Track ChatGPT, Perplexity, Claude and Gemini Referrals in GA4
GA4 can show you the visitors that ChatGPT, Claude, Perplexity and Gemini send to your site, but only if the session source is read correctly. Google now ships a default "AI Assistant" channel, and a…
Content Signals in robots.txt: 117 of 799 Sites Declare One
Of 799 sites in our scan database on 2 November 2026, 117 serve a robots.txt with a ContentSignal line 14.6%. Among the 677 sites that serve a usable robots.txt at all, that is 17.3%. Another 682…
Your RSS Feed Returns 403 to Feed Readers and Agents: Cloudflare and Firewall Rules That Block It
Cloudflare's Bot Fight Mode and its "block AI bots" switch can answer your RSS feed with a 403 challenge page, and a feed reader or AI agent has no way to solve one. On 1 November 2026 we requested…
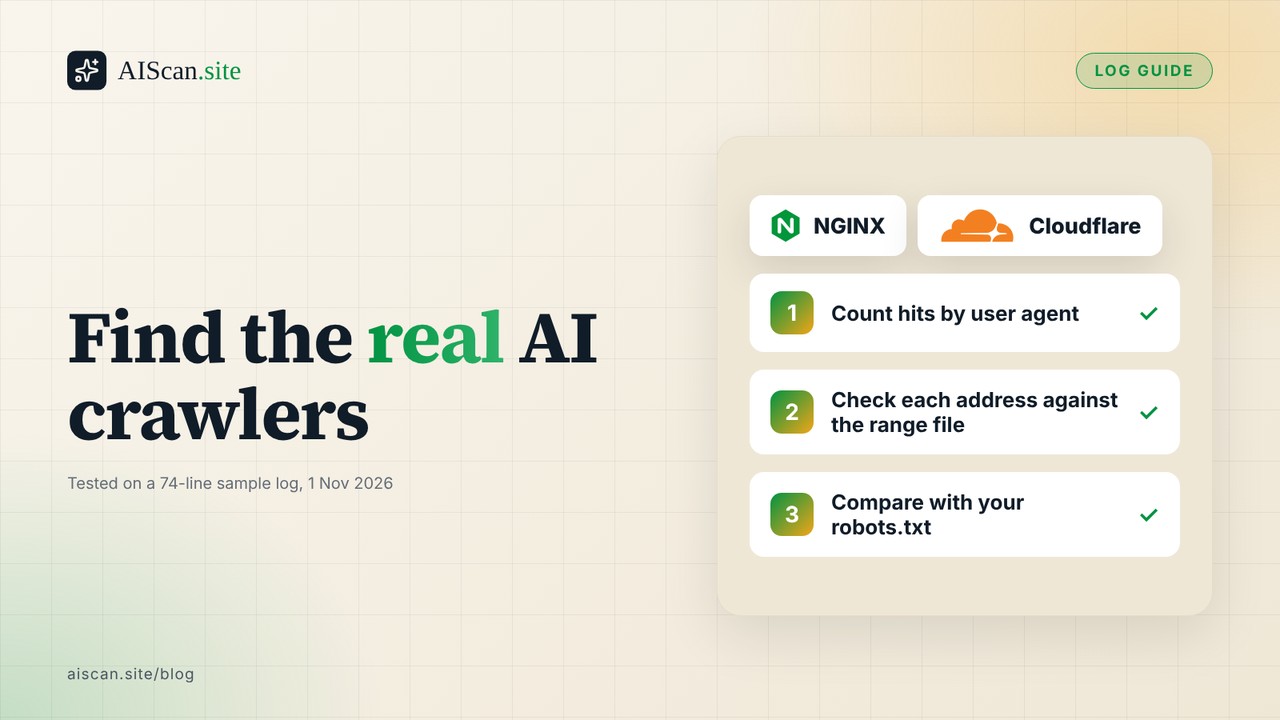
Find AI Crawlers in Your Server Logs and Verify Them
Your analytics tool will not tell you which AI crawlers visit your site, because a crawler that fetches the HTML and leaves does not run its script. Only the server or the edge in front of it sees…
We Run a Public MCP Server: 67 Days of Who Calls It, and How
We run a public MCP server, and for 67 days we have been counting who uses it. Between 26 August and 1 November 2026, AI assistants asked it for scans 375 times, which is 10.1% of the 3,723 scans…
ChatGPT Says It Can't Access Your Website: Five Causes and How to Tell Which
When ChatGPT says it cannot open your page, one of five things happened, and a short script of four curl requests sorts four of them in about a minute. The fifth is that ChatGPT never tried. This…
Block Fake AI Crawlers From Probing .env and .git Files
Some of the traffic that calls itself GPTBot or ClaudeBot is not a crawler. It is a scanner that borrowed a famous name and asks your server for /.env, a .git folder or a wpconfig.php.bak. The fix is…
Web Bot Auth Key Directories: 78 of 797 Sites Answer 200, and Most Are Soft 404s
Of 797 sites in our scan corpus, 78 answer HTTP 200 at the Web Bot Auth key directory path. That is 9.8%. The number sounds like early adoption, and it is not. 53 of those 78 sites also fail our…
Your robots.txt blocks everything by accident: find the leftover Disallow: / and stop it coming back
If your robots.txt says Useragent: followed by Disallow: /, every crawler that obeys the file is told to stay off your whole site. It takes one line to cause and about a minute to find, and Google's…
IndexNow Setup: Tell Search Engines the Day You Publish
IndexNow lets you tell Bing, Yandex, Naver, Seznam, Yep and Amazon about a new or changed URL the moment it exists, with one HTTP request and one key file on your own domain. It does not reach…
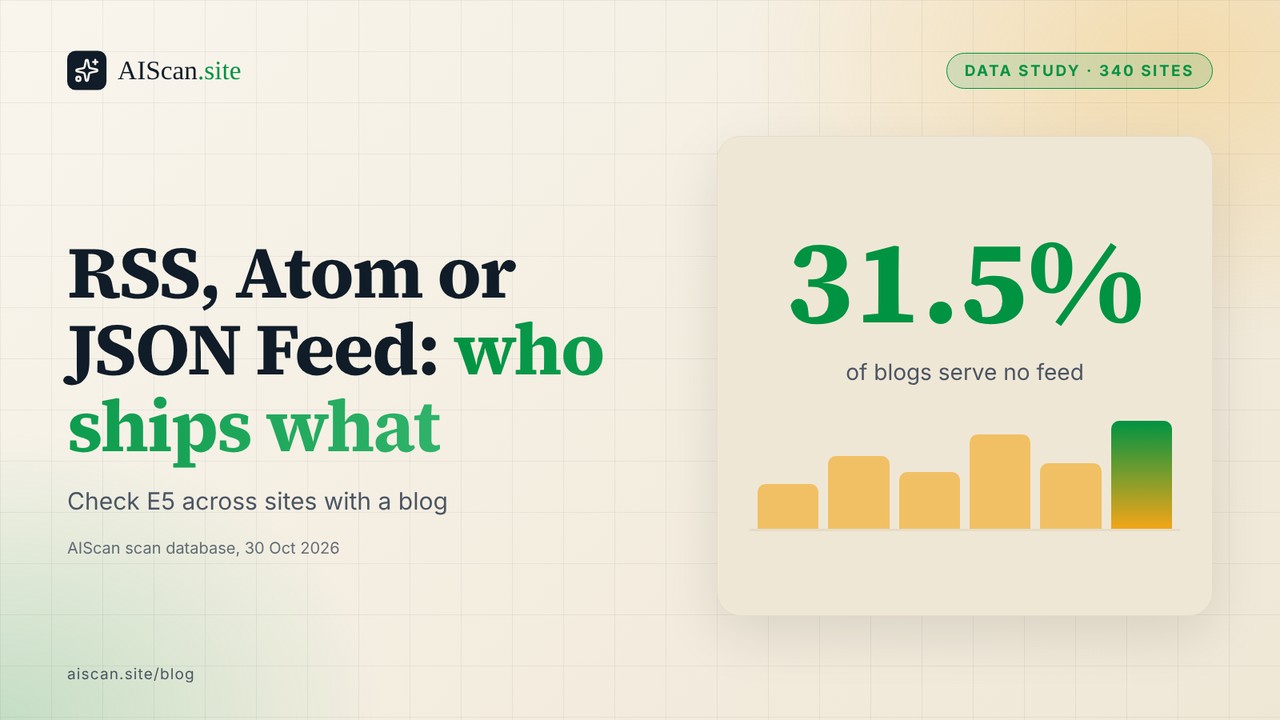
RSS, Atom or JSON Feed: What 340 Sites With a Blog Actually Ship
Of the 340 sites in our scan corpus that have a blog, news or articles section, 233 serve a feed, and 191 of those feeds are RSS. Atom is on 6 sites. JSON Feed was reported on 36, but most of those…
Fix "Heading elements are not in a sequentially-descending order" without breaking your design
Lighthouse prints "Heading elements are not in a sequentiallydescending order" when a heading jumps more than one level, for example an <h4 straight after an <h2. The fix is almost never to delete…
llms.txt Content-Type and Charset: What to Send and How to Check
Send llms.txt as text/plain; charset=utf8 or text/markdown; charset=utf8, with no byte order mark, and always spell out the charset. The type decides whether a client treats the file as text at all.…
Does robots.txt Need a Sitemap Line? 782 Sites Show What Happens
Of 782 sites in our scan database on 29 October 2026, 572 serve a robots.txt that declares a sitemap, 89 serve a robots.txt with no Sitemap line, and 121 fail the robots.txt check outright. Declaring…
JSON-LD in Google Tag Manager is missing from your served HTML: test it and move it server-side
If your JSONLD is added by a Google Tag Manager Custom HTML tag, a plain HTTP fetch of your page contains zero schema blocks. Google can still read it, because Googlebot renders JavaScript. Crawlers…
One h1, title, meta description and JSON-LD on Ghost, Lovable, Next.js, Replit, Webflow, Wix and WordPress
One page needs one <h1, a <title, a meta description and a JSONLD block, and AIScan check C3 structured HTML passes only when all four are in the HTML the server returns. Who writes each of the four…
Serve Markdown to agents with a Cloudflare rule
To serve Markdown to AI agents from a site on Cloudflare, turn on Markdown for Agents for the zone Dashboard AI Crawl Control or for one path with a Configuration Rule. When a client sends Accept:…
How Big Is an llms.txt? Size and Structure Across 779 Real Sites
Of the 779 sites in our scan database on 28 October 2026, 427 served an /llms.txt file that returned a 200, and the typical file that passes our check is small: a median of 4,403 bytes, with 80% of…
Fix soft 404s on Astro, Docusaurus, Lovable, Next.js, Webflow and Wix
A soft 404 is a page that says "not found" while the status line says 200. On the six platforms below, the default behaviour ranges from a correct 404 with a deadend body Webflow, Wix, Docusaurus…
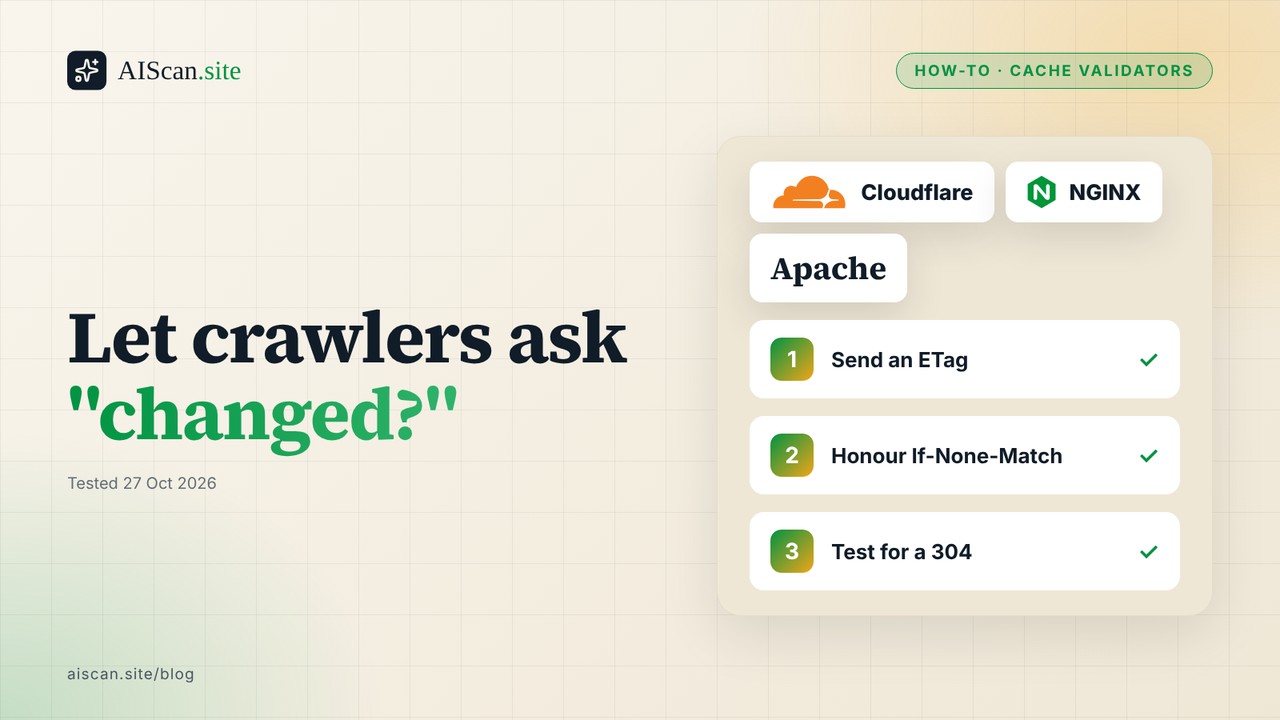
Add ETag and Last-Modified so crawlers can send conditional requests
To make a page answer 304 Not Modified, send an ETag or a LastModified header on the first response, then answer a repeat request that carries IfNoneMatch or IfModifiedSince with status 304 and no…
Fake AI Crawler Traffic: 63 Days of Our Own Server Logs
Of the 2,107 requests our own logger recorded under an AI crawler's name between 25 August and 27 October 2026, 61.6% came from 22 sources that each used 10 to 15 different crawler names, and not one…
Why /.well-known/ files return 404 or 403 on your host, and how to fix it
Your /.wellknown/ file is returning 404 or 403 because something between your repository and the browser treats a folder that starts with a dot as private. In our tests on 26 October 2026, a default…
llms.txt on Astro, Docusaurus, Framer, Ghost, Hugo, Next.js, Replit, Shopify, Squarespace, Webflow and Wix
Updated on 26 October 2026. Every platform section was checked on the dates shown inside it. Squarespace, Webflow and Wix joined this guide on 26 October 2026, so all eleven platforms that had their…
Set Up Cloudflare AI Crawl Control: Allow, Block, Verify
If your site sits behind Cloudflare, you can allow or block each AI crawler from one table in the dashboard, and Cloudflare turns every block into a single WAF custom rule on your zone. The setting…
AI readiness setup guide by platform (2026)
Verified 17, 18, 20 and 22 October 2026. Updated on 22 October 2026. An AIready site needs six things: a robots.txt that names AI crawlers D1, B2, a sitemap D2, a declared feed E5, an llms.txt C2,…
Serve robots.txt with the right status and content type
Most robots.txt advice is about the rules inside the file. This guide is about the envelope: the HTTP status, the content type, the redirects and the size. A perfect set of rules does nothing if the…
What a Failing AIScan Check Really Says: 2,961 Fail Lines Audited
A failing check on a scan report is supposed to be an instruction. The site owner reads the line, knows what the scanner asked for, knows what came back, and knows what to change. We audited whether…
Rate-limit AI crawlers without blocking them
Most advice on rate limiting AI crawlers stops at "add a limit". The part that costs you is where the limit applies and what it answers. A limit that covers /robots.txt and /llms.txt makes your own…
Which Agent-Readiness Checks Travel Together: 739 Sites, Three Bundles
Fix one agentreadiness check and a second one often moves with it. Fix another and nothing else changes. A scan report lists every check as its own line, so the reader cannot see which lines are…
Return HTTP 402 with an x402 payload on a paid resource
Most sites should not return a 402. If you sell nothing per request, skip this guide and keep your score. If you do charge for an API response, a report or a dataset, this is how to return an x402…
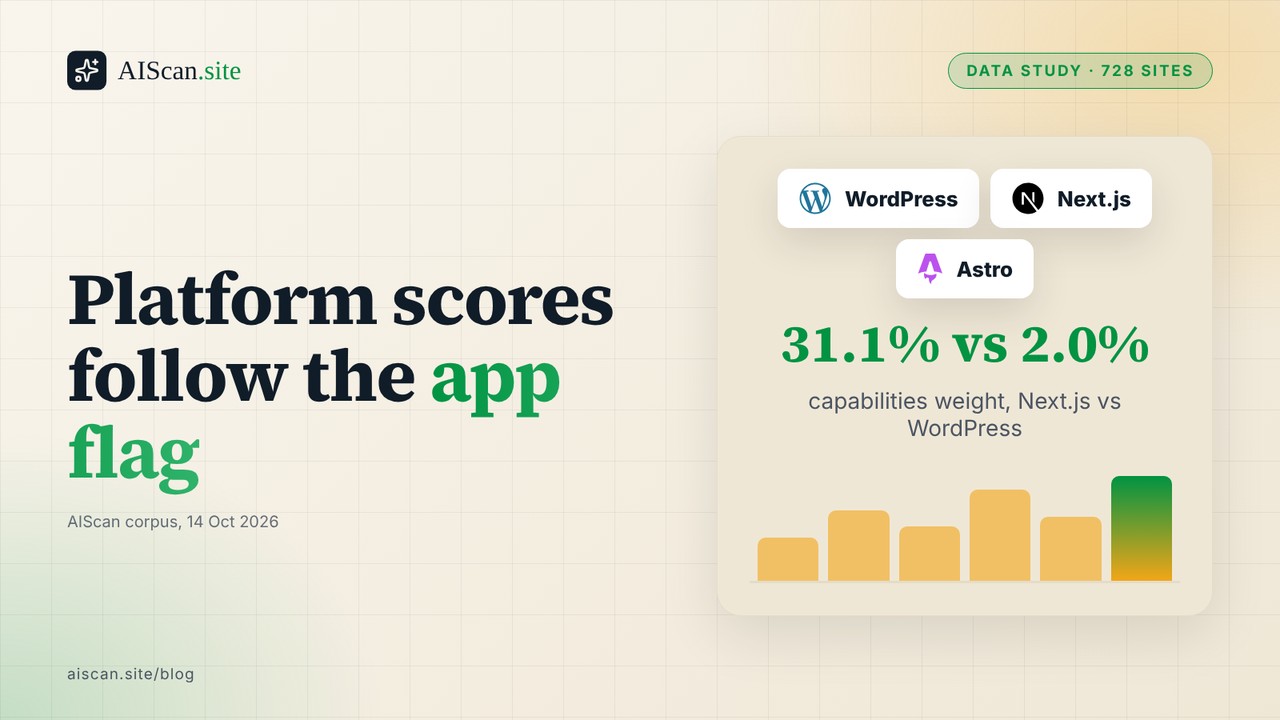
Platform League Table: WordPress, Next.js, Astro and Shopify Across 728 Sites
Every few weeks someone asks which platform produces the most agentready sites. WordPress, Next.js, Astro and Shopify all have fans, and a ranked table is the answer people expect. We have the data…
10 Best Instagram Profile Analyzers in 2026 (Tested)
Comparison of 10 Instagram profile analyzers with free plans, prices and AIScan AIreadiness scores, October 2026 Updated October 13, 2026. Prices, freetier limits and AIScan scores were all checked…
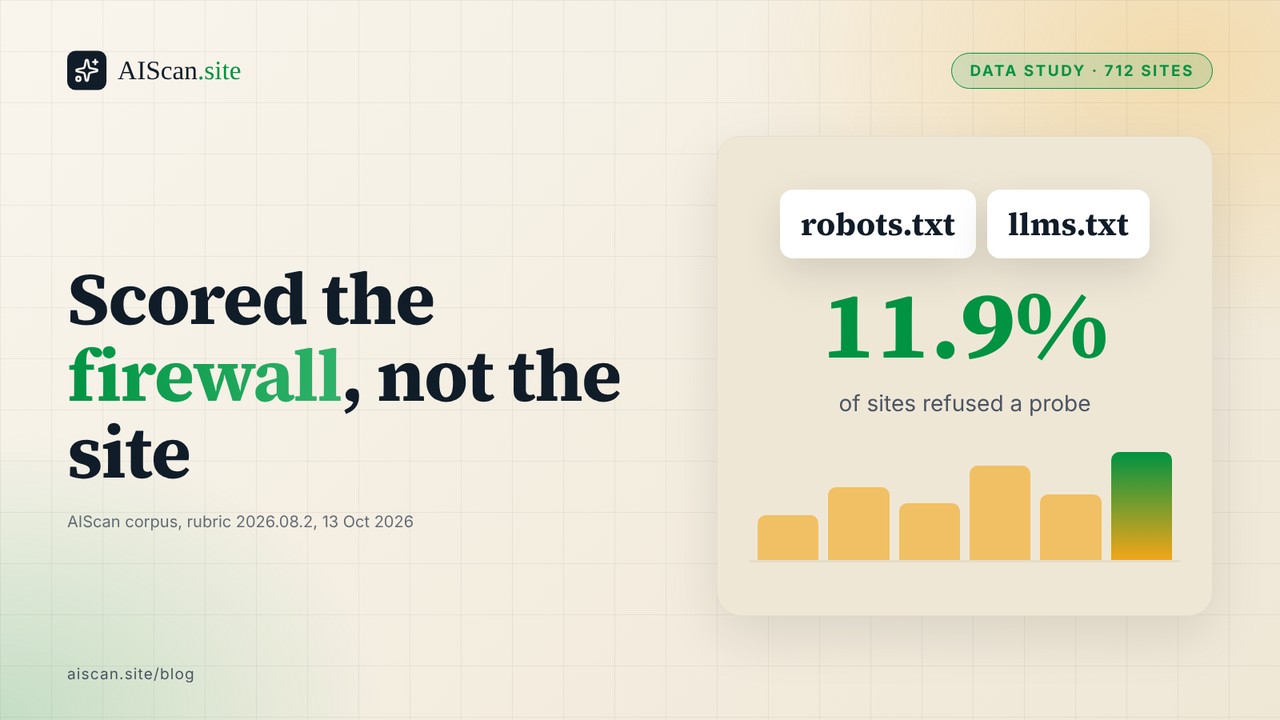
Blocked Probes: 85 of 712 Sites Scored the Firewall, Not the Site
A failing score has two possible meanings. Either the site does not have the thing, or the scanner never got to look. A scan report prints both as the same red mark, and the owner reading it cannot…
How to Publish an OpenAPI File AI Agents Can Find
An agent that wants to call your API has to know what it can ask for. An OpenAPI file answers that in one fetch: every path, every parameter, every response shape, in JSON a program can read.…
Which Checks Do Sites Fix? 349 Repeat Scans Compared
Most scanner posts tell you what to fix. Fewer tell you what people actually fixed. AIScan keeps every scan it has ever run, and many sites get scanned more than once, so we can answer a plainer…
Redirect www and http to one canonical host, the way an agent needs it
Type http://www.example.com/pricing into a terminal and count the hops it takes to reach the page. On a clean setup the answer is one, a single 301 straight to the canonical address. On many sites it…
Agent Discovery Files Census: P1, P3, P4 and E2 Across 835 Sites
Only 301 of the 835 sites in our scan corpus pass any one of four agentdiscovery checks that depend on a /.wellknown/ file or an API description. All four pass on 99 sites. Take out one platform and…
Declare your content-use policy to AI: Content Signals, ai.txt, TDMRep
Blocking or allowing a crawler answers one question: may it fetch this page. It says nothing about what the crawler may do afterwards. This guide covers the three places a site can state that second…
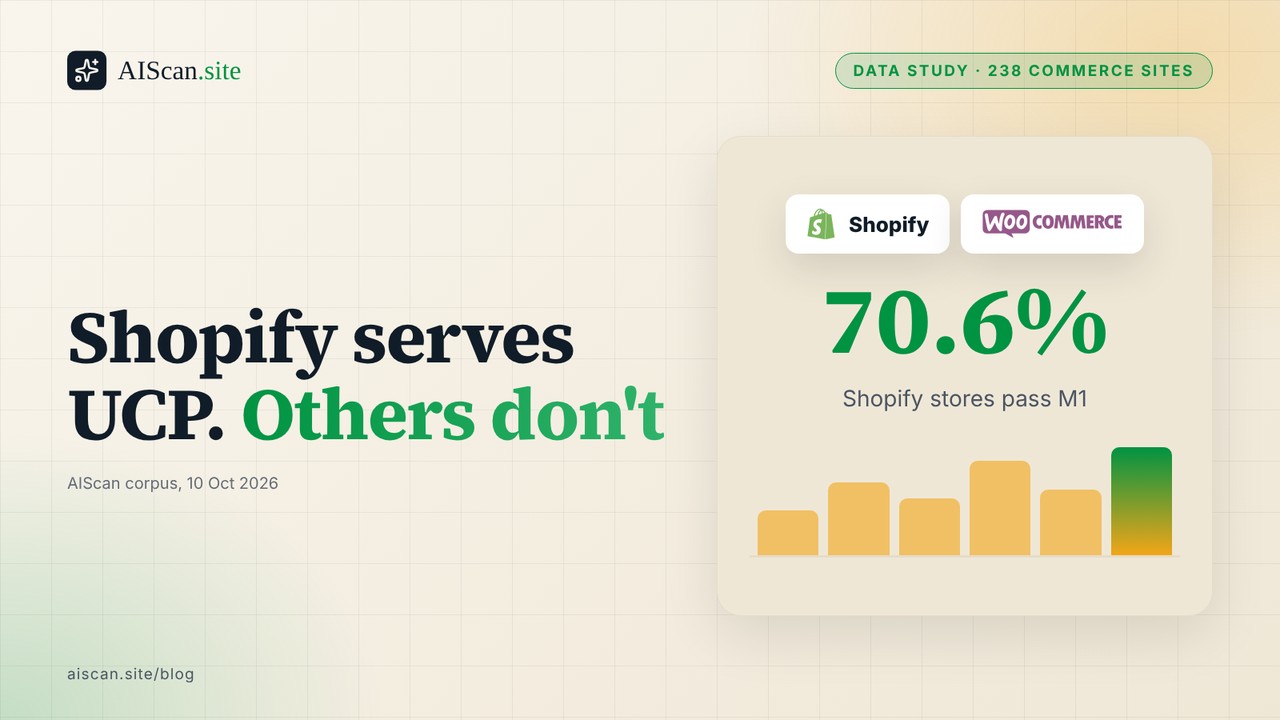
UCP profiles: Shopify serves one, most other stores don't
Shopify stores answer on /.wellknown/ucp. Almost nobody else does. We checked 238 commerceactive sites in the AIScan corpus on 10 October 2026: 12 of 17 Shopify catalogue stores pass check M1 the…
Monitor AI Readiness Over Time and Catch Silent Regressions
Discovery files rot without anyone touching them. A deploy overwrites robots.txt, a plugin update regenerates llms.txt, a CDN rule starts answering every unknown path with 200. Nothing errors, the…
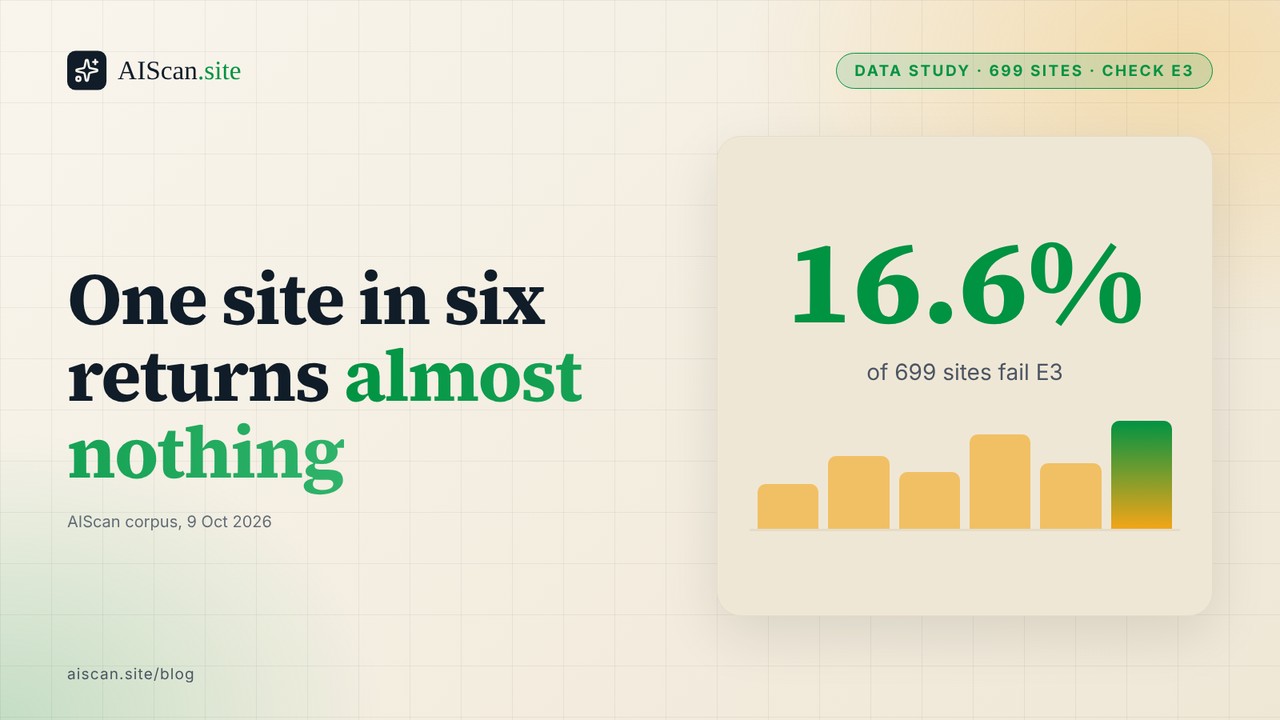
Server-Rendered Text and Headings: 16.6% of 699 Sites Fail E3
On 9 October 2026 we queried the AIScan database for check E3, the heading and serverrendered text check, across 699 distinct hosts. 498 of them 71.2% pass. 85 12.2% score partial. 116 16.6% fail,…
How to Test Whether an AI Agent Can Complete a Task on Your Site
Finding an MCP endpoint is the easy half. The half that matters is whether an agent can finish a job with it: ask a question, get an answer it can parse, and act on it. A server can answer tools/list…
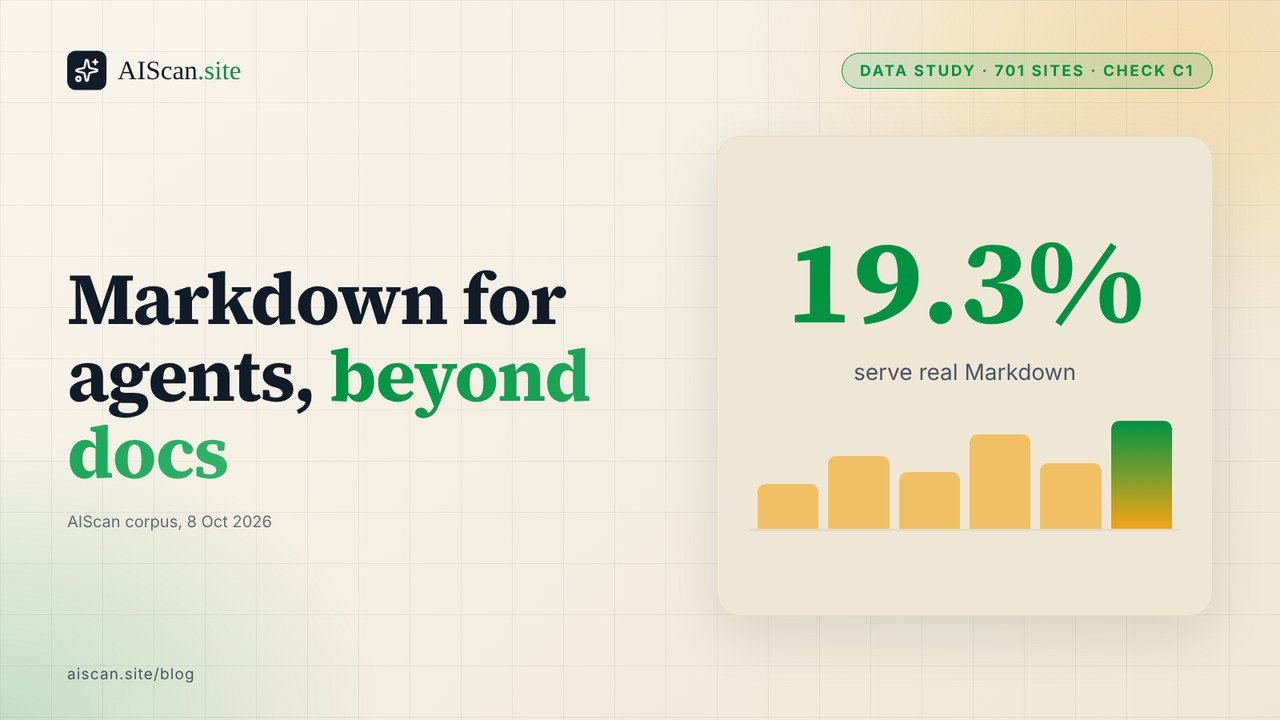
Markdown for AI Agents Beyond Docs: Only 19.3% of 701 Sites Serve It
On 8 October 2026 we queried the AIScan database for check C1, the Markdown availability check, across 701 distinct hosts. 135 of them 19.3% returned a real text/markdown response on one of the two…
Control which AI crawlers reach your site: a robots.txt starter
Most sites that "block AI" with a robots.txt file end up with one of two outcomes: a file that blocks nothing because a bot name is misspelled, or a file that blocks the crawlers that would have sent…
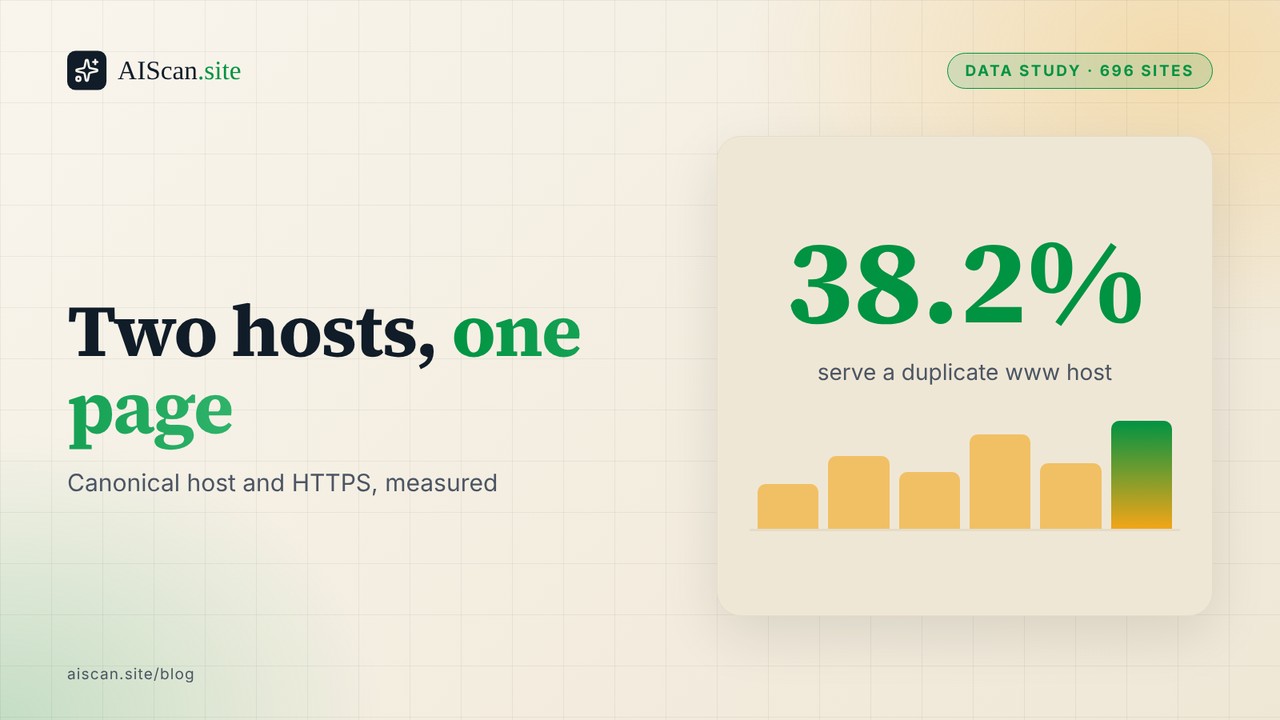
Duplicate www and apex Hosts: 38.2% of 696 Sites Fail the Canonical Check
On 7 October 2026 we queried the AIScan database for check E4, the canonical host and HTTPS check, across 696 distinct hosts. 405 pass. The other 291 are partial, and not one fails outright. The…
FAQ and Q&A schema that answers an agent's questions
Most FAQ schema advice is two years out of date. Google limited its FAQ rich result to government and health sites in 2023, then stopped showing it at all in May 2026. Plenty of guides still tell you…
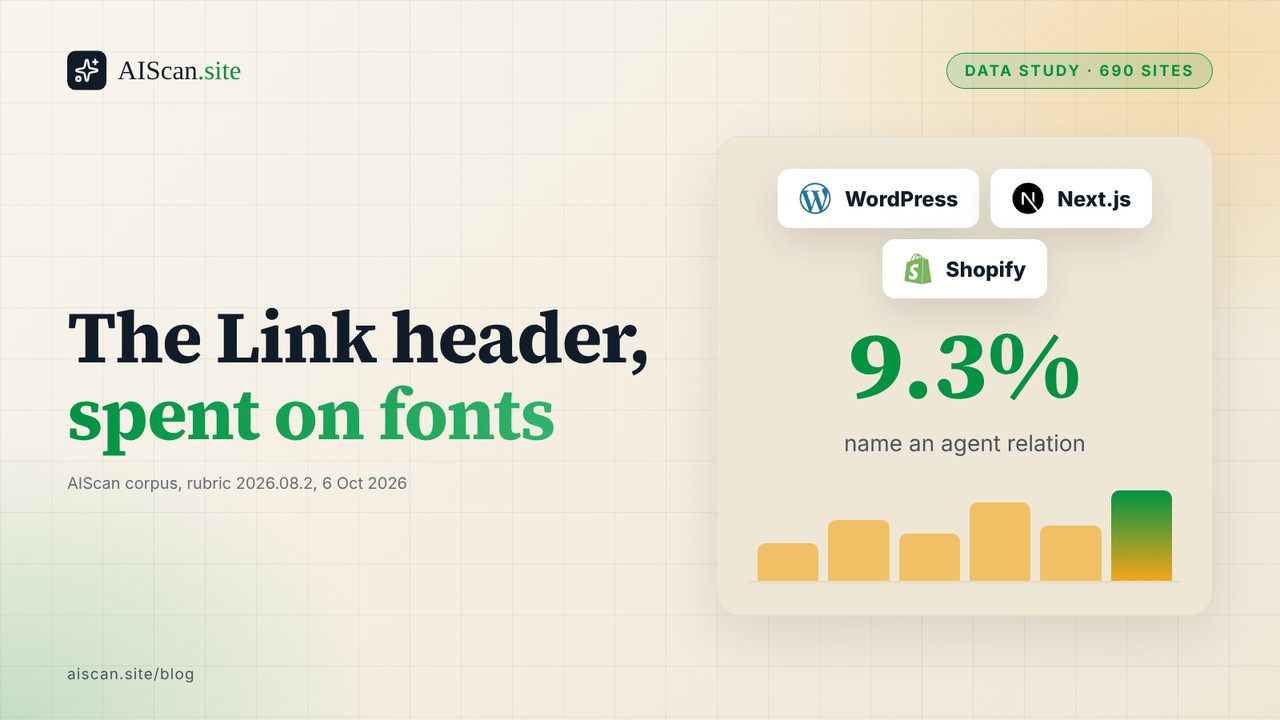
Link Header Discovery: Only 9.3% of 690 Sites Name an Agent File
Most sites send an HTTP Link header on their homepage. Almost none of them use it to tell an agent anything. On 6 October 2026 we queried AIScan's production database for the D3 check across 690…
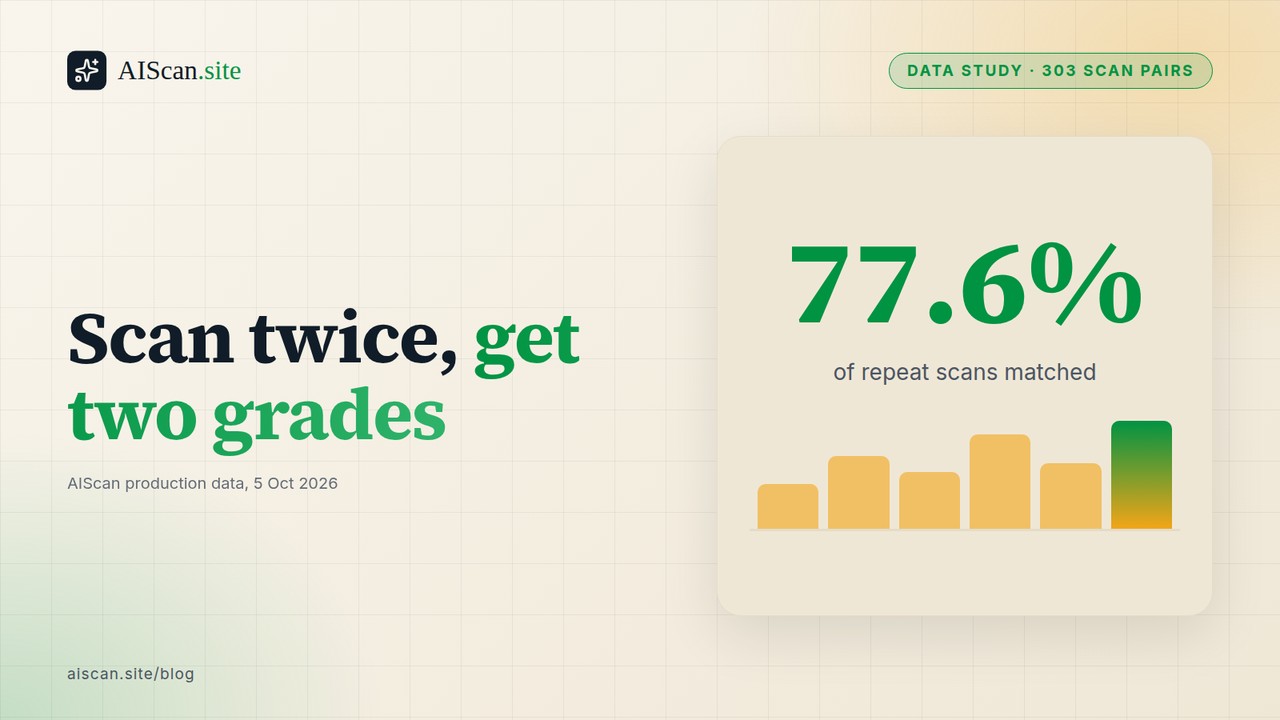
Does AIScan Give the Same Score Twice? 303 Repeat Scans Measured
Every scanner owes its users one answer before it asks for trust: if I run you twice, do I get the same grade? Most tools never publish it. We can, because AIScan keeps every scan it has ever run,…
Fetch Your Own Site the Way an AI Agent Sees It
Your site has at least three audiences: people in a browser, search crawlers, and AI agents. Servers can treat each differently, and the only way to know is to ask as each of them and compare the…
The Agent-Readiness Fix That Moves Your Score Most (2026): 681 Sites Ranked
Every agentreadiness checklist ends the same way: twentyodd items, all marked "important", no order. A site owner with one free afternoon cannot do twenty things, and nobody tells them which one to…
agents.md: What It Is and How It Differs from llms.txt
Ask three people what agents.md is and you get three answers. One says it is the file coding agents read in a repository. One says it is the Markdown page a store publishes for shopping agents. One…
Publish a Sitemap AI Crawlers Can Actually Find and Trust
A sitemap that returns 200 is the start of the job, not the end of it. Of 14 wellknown sites we fetched on 3 October 2026, 12 declared a sitemap in robots.txt. One of those, Stripe, serves its file…
Can Your Site Say "Nothing Changed"? ETag and Last-Modified on 300 Hosts
We probed 300 popular hosts on 3 October 2026, and only 77 of the 152 usable homepages sent a cache validator at all. That is 50.7%. Until a site sends an ETag or a LastModified header, no crawler,…
JSON-LD for AI: The Schema Types Worth Adding (C3, M4)
Most guides to structured data list thirty types and leave you to guess which ones matter. For a normal site, six are worth adding, and they fall into three groups: types that identify the site…
What Sites Tell GPTBot in robots.txt, and Whether They Mean It
We pulled robots.txt from 538 hosts in the AIScan scan corpus on 2 October 2026 and parsed 451 of them with a group parser that follows RFC 9309. The headline: 173 of the 451 files 38.4% name at…
Make a Page Answerable by AI: C1, C3 and E3 Fixes
An AI assistant that answers a question about your business does not read your page the way a visitor does. It receives the HTML your server sends, strips it down to text, and lifts whatever looks…
Your Sitemap Passes the Check and Still Fails Agents: 669 Sites Measured
A sitemap that returns HTTP 200 is not the same as a sitemap an agent can use. In AIScan's corpus of 669 sites, check D2 passes 499 of them 74.6%, and every one of those passes carries the same…
llms-full.txt: When a Full-Text File Beats a Link List
An agent that reads your llms.txt gets a map. To answer one question it then has to fetch three or four of the linked pages, one request each. llmsfull.txt removes that loop: it is one file with the…
How Many Sites Show an AI Crawler a Blank Page: 663 Measured
Of 663 sites in the AIScan corpus, 195 send an AI crawler an initial HTML document with no <h1 in it. That is 29.4% of the population, and it is the number the singleframework guides never add up.…
Link Headers for AI Agent Discovery: Set Up RFC 8288 Relations
An agent that lands on your homepage has already paid for the request. If that response can also say where your llms.txt, sitemap and API catalog live, the agent skips the guessing entirely. The…
What a Shopping Agent Can Read About Your Prices: 282 Sites Measured
An agent asked to compare three tools by price has two ways to answer. It can read a structured field, or it can read your marketing prose and guess. The howto on pricing…
OAuth Discovery for AI Agents: RFC 8414 and RFC 9728 Explained
An agent calls your API cold, with no token. Your server returns 401, and the agent has nowhere to go from there unless something on your domain names the authorization server it should talk to. Two…
Audit Your Own Agent Readiness From a Terminal in Ten Minutes
Paste your URL at aiscan.sitehttps://aiscan.site/ or run npx aiscancli yoursite.com and you get a score in under thirty seconds. Fine for a first read, not enough if you actually want to know what…
Publish an Agent Skills Index for Your Website
| If you want to… | Do this | Time | What it changes | ||||| | Give an agent a reusable, ondemand capability | Write a SKILL.md with name + description frontmatter, plus any scripts or reference…
The AI-Crawler Statistics Everyone Quotes, and Which You Can Actually Check
Every AIreadiness article, including plenty of ours, opens with a number: 78% of sites have a robots.txt, 28% publish an llms.txt, AI crawlers can't read JavaScript, one crawler is spoofed 17 times…
Web Bot Auth: Cryptographic Crawler Identity, Explained
Across the 499 sites in our own scan corpus, exactly 19 publish a working Web Bot Auth key directory. That's 3.8%. If you run any kind of automated client that fetches other people's sites a scraping…
How Stale Are AI Crawler IP Lists? We Checked All 15 Files
Every guide on verifying an AI crawler tells you to check its request against the operator's published IP range file. Almost none of them tell you when that file was last regenerated. The answer is…
Publish an API Catalog Agents Can Discover (RFC 9727)
Agents that want to call your API have to guess the URL today. RFC 9727https://www.rfceditor.org/rfc/rfc9727.html gives them a fixed place to look instead: /.wellknown/apicatalog, a small JSON…
The Soft 404 Problem: Why HTTP 200 Breaks Every Agent Discovery Check
Every convention on the agentic web works the same way: an agent asks for a file at a wellknown address, and a 200 means the file is there. /llms.txt, /robots.txt, a .md suffix on a documentation…
Add an RSS Feed AI Agents Can Actually Find
Two staticsite generators build you a feed with zero configuration. One declares it in <head on every site we tested. The other only manages it on five of every eight. Same defaulton feature, same…
Your llms.txt Is Sending AI Agents to 404s: We Measured It on Our Own Site
| Question | Short answer | ||| | What broke? | Our own llms.txt, parsed the way most link extractors parse Markdown, sent roughly 55% of nonscan agent traffic to a 404. | | Why? | The standard…
What a real 404 should return to an AI agent
You already know the first rule of a good 404: return status 404, not 200. That half of the check is a status line, and our own CIgate guidehttps://aiscan.site/blog/aiscancigategithubactions already…
Does Blocking AI Training Protect Your Content?
Too long, didn't read? Here's the honest version. | If you're asking... | The evidence says | What to do instead | |||| | Will blocking crawlers remove content already used for training? | No.…
Make your pricing machine-readable for shopping agents
Short answer: put a schema.org Offer block price, currency, availability, billing period on your pricing page, and check it with AIScan check M4. WooCommerce and Shopify emit it for you; Ghost and…
Publish an MCP Server Card So Agents Can Find Your Tools
On 10 September 2026 we probed every host running a remote MCP server listed in the official MCP Registry: 79 domains, three requests each. Seven of them publish a parseable server card at…
Docs Sites and AI Agents: Four Markdown Routes, 52 Sites Tested
Ask an AI assistant how to configure a webhook, add a database index, or set a cache header, and it does not go looking for a blog post. It goes to the vendor's documentation. Docs are the…
Gate AI readiness in CI so a regression fails the build
A green pipeline is supposed to mean the site is fine. On an AI readiness check it often means something narrower: that the gate could not tell a file from a phantom. This step, which appears in a…
Stealth Crawling vs User-Driven Fetching in 2026: What 75 Sites Actually Do
On 4 August 2025 Cloudflare removed Perplexity from its verified bot list and published the evidence. Perplexity's answer was that fetching a page because a person asked for it is not the same act as…
The Agentic Commerce Stack in 2026: UCP, ACP, AP2 and x402, Measured on 30 Storefronts
Five protocol names now compete for the same sentence in every agentic commerce explainer: UCP, ACP, AP2, x402 and MPP. Almost every explainer treats them as rivals. They are not. Four of the five…
Google AI Overviews in 2026: What You Can Actually Control, Measured on 110 Publishers
Search Console will tell you that AI Overviews sent you traffic. It will not tell you how to turn them off, because there is no setting to turn off. Google publishes exactly four controls that reach…
Cloudflare Pay Per Crawl in 2026: Should You Charge AI Crawlers? 119 Sites Measured
Stack Overflow will sell you its homepage for fifty cents. Point an AI crawler at it and the server answers HTTP 402 Payment Required, crawlerprice: USD 0.5, and a JSON body naming Cloudflare's Pay…
AI Crawler Traffic in 2026: Only 51.8% of Sites Can Answer "Nothing Changed"
Verified 5 September 2026. All measurements in this article were taken on that date. Every AI crawler that visits your site asks the same handful of questions over and over. Where is your robots.txt.…
llms.txt vs robots.txt vs sitemap.xml in 2026: Six Files, Six Jobs
Verified 4 September 2026. Every figure below was measured or fetched on that date. Three files keep getting compared as if they were competing for the same job: robots.txt, sitemap.xml and llms.txt.…
The State of AI Agent Readiness in 2026: 473 Sites Measured
Half of the web's agentreadiness problem is already solved, and almost nobody has noticed which half. Across 473 real websites scanned by AIScan between 24 August and 3 September 2026, the median…
WebMCP in 2026: Do You Actually Need It Yet? 85 Sites Measured
Verified 2 September 2026. Every number below was measured on this date against live sites. The honest answer to "do I need WebMCP yet" turned out to depend on a question nobody asks first: is it…
Is Your llms.txt Valid? 39 Real Files Tested, and the 11 Mistakes That Break Them
Verified 1 September 2026. Every figure here comes from a live fetch on that date. We fetched /llms.txt from 50 wellknown sites, kept the 39 that returned a real file, and ran every one against the…
Cloudflare Agent Readiness vs Chrome's Agentic Browsing Audit in 2026: 28 Checks, One Overlap
Verified 31 August 2026. Every score, status code and audit weight below was produced on this date by running both tools live. The Lighthouse figures come from Lighthouse 13.4.1 driving Chrome for…
AI Readiness Scanner Pricing in 2026: Every Price, Verified and Dated
Verified 30 August 2026. Every price below was fetched from the vendor's own pricing page on this date. Where a vendor publishes no price, that is recorded as a finding rather than filled in with a…
The 10 Best AI Agent Readiness Scanners in 2026, Tested on One URL
Verified 29 August 2026. Every score below was captured from the tool's own public endpoint on that date, and every disagreement was adjudicated by hand against the live site. A category of tool has…
Your Next.js Site Ranks on Google and Is Invisible to ChatGPT: How to Prove It
Googlebot runs your JavaScript. The crawlers that build ChatGPT's and Claude's indexes, as far as anyone has measured, do not. That gap is why a React or Next.js site can hold page one on Google and…
AI Crawler User-Agents 2026: Verified List and IP Ranges
Updated on 12 November 2026: every IP range file refetched and recounted, and every reverseDNS test rerun. The short answer: the AI crawlers that matter in 2026 come from OpenAI, Anthropic, Google,…
Does llms.txt Actually Work in 2026? Google Ignores It, Chrome Audits It, 97% Get Zero Requests
Updated 26 August 2026. In June, Google added a line to its own AI search documentation saying that Google Search ignores llms.txt files. Two months earlier, a different Google team shipped a…
Search, Agent, Training: What Cloudflare's Three AI Crawler Categories Actually Control
Updated 25 August 2026. Cloudflare now sorts crawler behaviour into three categories you can configure — Search, Agent, and Training — and the setting you pick for each decides whether Google indexes…
Cloudflare's AI Bot Block Is About to Catch Googlebot: What Changes on 15 September 2026
Update — 28 September 2026: the 15 September migration landed, and it did not go the way this article predicted. Cloudflare's own followup post, "Introducing an Accountable designation for AI…
Best AI Readiness Checkers 2026: 8 Tools Re-Scanned | AIScan
Updated on 10 November 2026: every tool's own site was rescanned, and the Cloudflare section now matches Cloudflare's launch post. Your site can rank on page one of Google and still be invisible to…
Best AI Agent-Ready Tools 2026: 10 Tools Scanned | AIScan
The best AI agentready tool depends on which job you need done. To find out whether ChatGPT, Claude and Perplexity mention you, use a visibility tracker such as Profound, Otterly.AI or Semrush. To…